
End-to-end tests · web, Android, CLI tools and Electron
Plain-English end-to-end tests.AI writes each test once. Every run after that uses none.
What you get
So a 20-test run costs 2¢ and gives the same answer every time. Web, Android, CLI tools and Electron apps, in our cloud or on your own machine. For developers and teams without a QA engineer.
Start
100 credits a month · no card
The problem
- Flaky end-to-end tests nobody has time to fix.
- AI testing tools that charge 12–40¢ every single run.
- Tests locked in a vendor's cloud. When Octomind shut down, its users lost their runs.
See a run
Pick a screen. Write and Run are the real run in Fig. 1.

Test my app · describe it
Say what should work
Your words Dictate
Creating a project is the core action of the app, so we want to be sure it is really saved and not just shown. Log in as the seeded user (use the shared login flow, flows/login.test.md). On the dashboard click "Create project"; a dialog titled "New project" should open. Type Q3 roadmap into the "Project name" field and click "Create". A message saying "Project created" should appear and the projects list should show "Q3 roadmap". Then reload the page: after the reload the projects list must still show "Q3 roadmap", otherwise the project was never persisted.
9 AI calls for $0.0015, lint-cleanDraft the steps
tests/create-project.test.mddraftdrafted
- ---
- name: A new project is saved
- tags: [smoke, projects]
- start: /login
- setup:
- - request: POST /__test/seed
- ---
- 1. Use: flows/login.test.md
- 2. Click "Create project"
- 3. Expect: a dialog titled "New project" is open
- 4. Fill "Project name" with Q3 roadmap
- 5. Click "Create"
- 6. Expect: a message says "Project created"
- 7. Expect: the projects list shows "Q3 roadmap"
- 8. Reload the page
- 9. Expect: the projects list shows "Q3 roadmap"
Live run · replay-only · Acme Shop · local
Replaying 1 testNothing failed
A new project is saved13 steps
| # | Step | Status | Time |
|---|---|---|---|
| 1.1 | Go to /login | queuedrunningpassed | 52 ms |
| 1.2 | Fill "Email" with {{params.email}} | queuedrunningpassed | 34 ms |
| 1.3 | Fill "Password" with {{params.password}} | queuedrunningpassed | 50 ms |
| 1.4 | Click "Log in" | queuedrunningpassed | 74 ms |
| 1.5 | Expect: the page heading is "Dashboard" | queuedrunningpassed | 5 ms |
| 2 | Click "Create project" | queuedrunningpassed | 52 ms |
| 3 | Expect: a dialog titled "New project" is open | queuedrunningpassed | 4 ms |
| 4 | Fill "Project name" with Q3 roadmap | queuedrunningpassed | 31 ms |
| 5 | Click "Create" | queuedrunningpassed | 512 ms |
| 6 | Expect: a message says "Project created" | queuedrunningpassed | 5 ms |
| 7 | Expect: the projects list shows "Q3 roadmap" | queuedrunningpassed | 3 ms |
| 8 | Reload the page | queuedrunningpassed | 39 ms |
| 9 | Expect: the projects list shows "Q3 roadmap" | queuedrunningpassed | 971 ms |
This run
- Trigger
- cli · replay-only
- AI calls
- 0 · replays use no AI
- Cost
- $0.00
- Engine
- 0.1.0
Results › example › Add to cart
Add to cart healed
The one line that matters
Step 2 was repaired: the 'Add to cart' button is now 'Add to bag'. Review the fix.
1 fix to review AIwaitingapproved
Never applied silently. Until you approve, the test keeps its original step. A heal can change how a step is done, never what is checked. Heals are free.
Before · your step
2. Click "Add to cart"
After · AI repair
2. Click "Add to bag"
What is checked: unchangedApprove
Proof
After: the cart shows 1 item
feat: discount codes #42
Open 3 commits into main from feature/discounts
optestra bot commented · edited
Optestra: running 2 tests against the preview…
Optestra: Failed · demo-shop · staging
| Passed | Healed | Failed | Flaky | Blocked |
|---|---|---|---|---|
| 1 | 0 | 1 | 0 | 0 |
2 tests in 16.1s · 0 AI calls · $0.00
What went wrong
Failed: Expected order total '$90.00', found '$100.00'
product bug · affects 1 test: Discount code takes 10% off
✕Tests 1 failed, 1 passed
✓build Successful
Write once.Replay for pennies.
Three steps. Only the second one uses AI.
1Write
Write it, or say it.
Type steps in plain English, one per line. Or describe the test in a paragraph, or speak it, and the app drafts the steps for you to read.
2Record
AI writes it once.
The first run works out each step in a locked-down browser and saves exactly what it did, as a file in your repo. That is the only run that uses AI.
3Replay
Every run after replays it.
No AI, no surprises. Each
Expect:line is checked by code, and a run of up to 20 tests costs 2 credits (2¢).
New · version comparison
Did v2 breakwhat v1 did?
Run the same plain-English tests against two versions of your CLI tool or app, and get the regressions in one report. Free on your own machine.
optestra compare --base correct --head broken-fewer-results
| Test | correct | broken-fewer-results |
|---|---|---|
| tests/sort-orders.test.md | ✓ order rows: 5 | ✗ order rows: 3 (−40%) |
1 regression(s) between correct and broken-fewer-results.

Measure regressions:
tests/sort-orders.test.md order rows: 5 → 3 (-40%)What you can test.In our cloud or on your machine.
Web, Android, CLI tools and Electron apps, in our cloud or on your own machine. Native desktop apps are coming, on your own machine.
Websites
Any public address or preview deploy.
Chromium, Firefox and WebKit at desktop, tablet and phone sizes. Saved logins, 2FA codes and a hosted test inbox.
- In our cloud
- Yes
- On your machine
- Yes
Android apps
Upload your APK. A fresh emulator for every test.
Android 13 to 17, phone or tablet. In the cloud, 2 credits a test (at least 10 a run).
- In our cloud
- Yes
- On your machine
- Yes
CLI tools
Test a command-line tool in plain English, and compare two versions.
Version comparison is free on your own machine.
- In our cloud
- Coming soon (paid plans)
- On your machine
- Yes
Electron and Tauri apps
Electron apps on every OS, Tauri apps on Windows.
On your own machine.
- In our cloud
- No
- On your machine
- Yes
Native desktop apps
Windows, macOS and Linux apps.
Coming, on your own machine.
- In our cloud
- No
- On your machine
- Coming
Runs on your own machine can show up in your dashboard, free.
Who it's for.If you ship, and nobody tests.
Developers and teams without a QA engineer.
Solo developers
Cover your critical flows in an afternoon. Run them on every push for a few cents.
Start freeStartup teams with no QA
Anyone can write a test in English. Every pull request is checked before it merges.
Start freeAgencies
One readable test suite per client site, checked on every deploy. No seat pricing.
Start freeComing from Octomind, Cypress, Playwright or mabl
We'll migrate your first 10 tests free.
Migrate my first 10 tests
What "checked" means
A row forevery line.
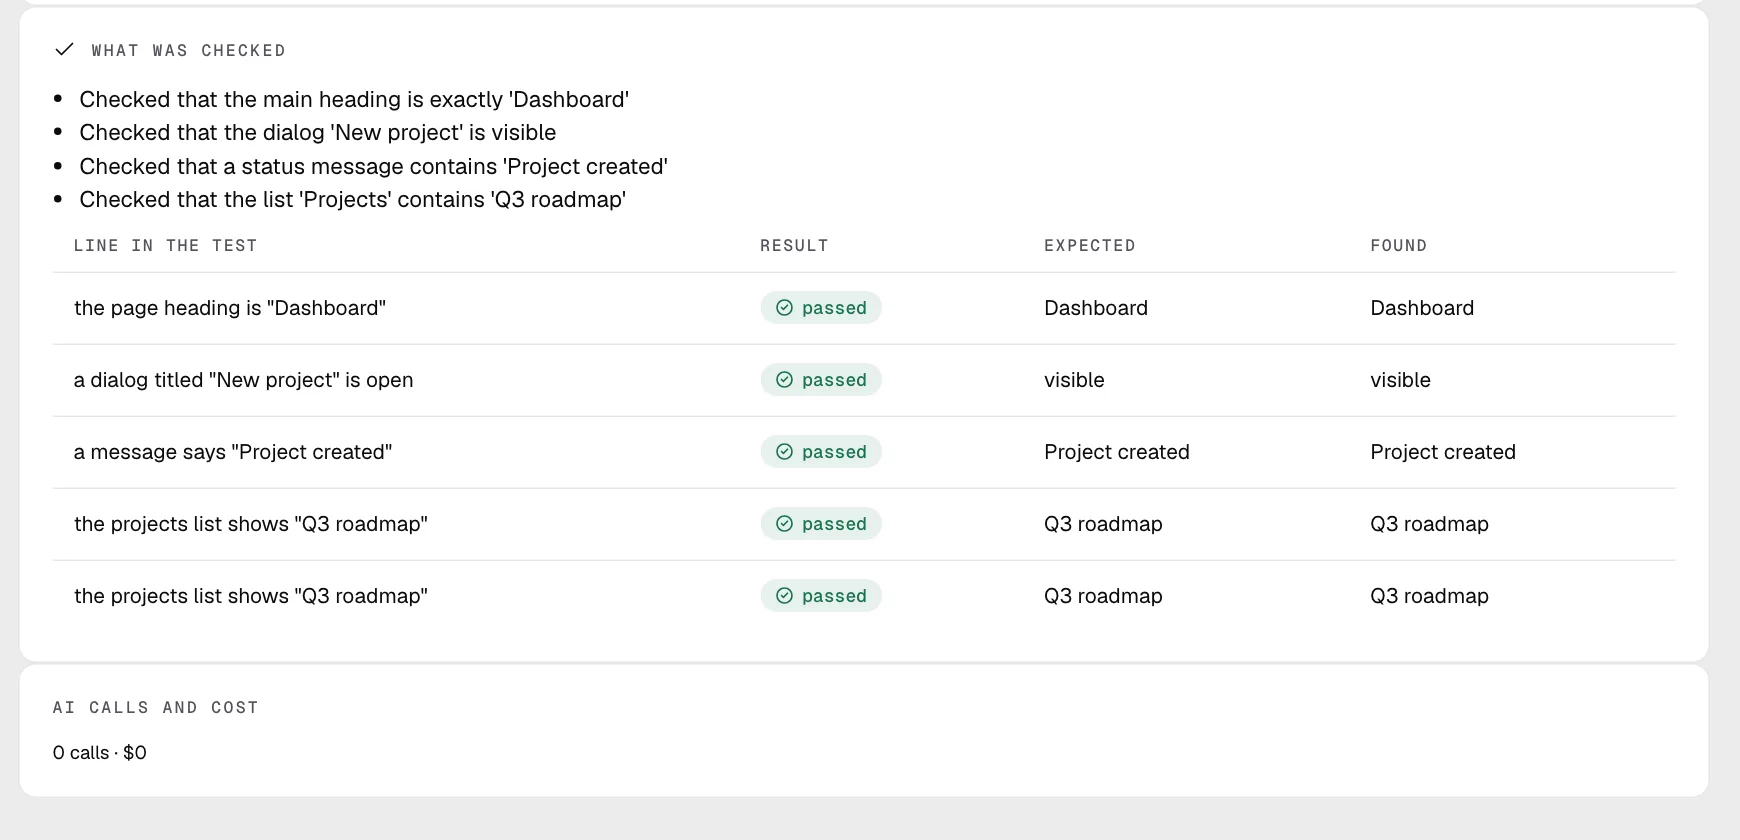
This is the check table of the run in Fig. 1, straight from the app. Each line in your test is a row: what the test said, what was expected, what the page showed. Code evaluates it on every replay, and your AI never sees the verdict.
Measured.With the date and the method.
Bench: fixture apps with real bugs, and a score for what our AI got wrong. Real numbers from 2026-10-08.
0
False passes
on step-written tests, in 15 replays of buggy builds.
0
AI calls
on every replay of an unchanged app. AI only writes a test or proposes a heal.
11/11
Step-written tests
authored correctly by the hosted AI.
Single runs on fixture apps · DeepSeek-V4.1-Flash via OpenRouter and DeepInfra · engine commit 5ab6cf2 · every number, including the ones that don't flatter us
What we won'tcompromise.
Six promises. Each one is a design decision, not a slogan.
Green means green.
Every Expect line becomes a typed check that plain code evaluates. A model never decides pass or fail, and a check is tested to be able to fail.
No AI, no surprises, on every replay.
A replay uses no model: same steps, same speed, same result, at the price of a browser for a few seconds.
Your tests are yours.
Plain Markdown files in your repository. Every website test is also a Playwright spec that runs without us, and the engine is open source (MIT).
No silent fixes.
When your app changes, a heal is proposed with its diff and its proof. Nothing is fixed silently, and no heal can change what is checked.
Clear about data.
Our AI is pinned to one provider with zero data retention and no fallbacks. Secrets are typed by the runner and never seen by a model.
Nothing to set up.
Nothing to install and no command line in our cloud. Paste a URL, write a sentence, press Run.
Cheap to start.Cheap to keep.
1 credit is 1 cent. Every feature is on every plan, except cloud CLI runs, which are coming soon to paid plans.
Switching tools?
We'll migrate your first 10 tests,free.
Send us your existing tests (Octomind export, Cypress, Playwright, mabl) or a list of your key flows. We rewrite your 10 most important as plain-English tests, run them against your app, and hand them over within 2 working days.
Questions
The honestanswers.
Does every run use AI?
No. The first run works out the steps and records them. Later runs replay the recording with no AI, so a cloud run costs a couple of credits and the same result every time. AI comes back only for a new or changed step, or when your app changed and a step needs healing, and then it proposes a fix for you to review. How a run works.
Can the AI make a failing test pass?
No. Each Expect line becomes a typed check that plain code evaluates, and the verdict is computed from the checks. The AI works out how to do a step, never whether it passed. A heal can change how a step is done, never what is checked, and it is shown to you for review. Checks and verdicts.
What if you disappear?
Nothing breaks. Your tests are Markdown files in your own repository, the engine that runs them is open source (MIT) and runs on your machine or in your CI, and every recorded website test is also a plain Playwright spec that runs without Optestra. The cloud, the app and hosted AI are the paid parts; your tests don't depend on them. If Optestra disappears.
Playwright's test agents are free. Why would I pay?
You might not. Playwright's planner, generator and healer are good, free and open, and if your team is happy owning Playwright code they may be all you need. We are different in what you keep: the test is an English file anyone can read, each Expect is a checked-by-code assertion, heals are proposals you review, and the same file runs on Android. We also host the browsers and emulators, PR checks and inboxes, so there is nothing to set up. And because every website test exports as a Playwright spec, choosing us doesn't close the other door. Playwright test agents vs us.
Say what should work.We'll test it.
Built so your first passing test takes about five minutes. 100 free credits a month, no card.